AI Share of Voice is the percentage of brand recommendations, mentions, and citations your company captures across generative engine responses compared to total market competitors. As buyers shift from browsing search results to asking conversational engines for software recommendations, AI Share of Voice replaces traditional organic search impression share.
Traditional search visibility tracks keyword ranking distributions on Google. AI Share of Voice calculates whether generative models recognize your company as a primary category solution when answering unbranded discovery queries.
What Is the Mathematical Formula for AI Share of Voice?
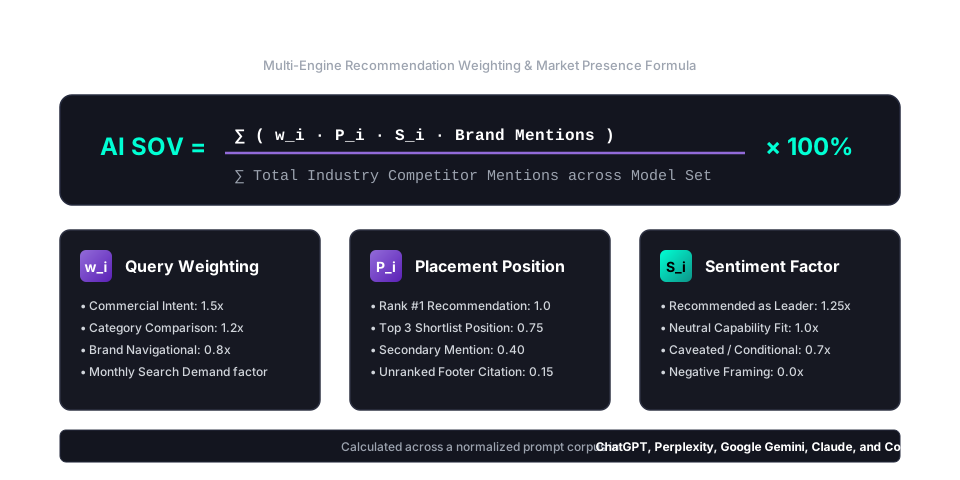
The mathematical formula for AI Share of Voice divides your brand's weighted recommendation score by the total weighted recommendation scores of all tracked category competitors across a standardized prompt portfolio.
AI SOV = [ Σ (w_i × P_i × S_i × M(Brand, Q_i)) / Σ Σ (w_i × P_i × S_i × M(Competitor_j, Q_i)) ] × 100Where the individual variables are defined as follows:
N: Total number of sampled buyer prompts in the evaluation portfolio.K: Total number of evaluated competitor brands within the product category.w_i: The intent weight assigned to prompt Q_i based on commercial purchase value.P_i: The placement score reflecting where the brand appeared in the synthesized answer.S_i: The sentiment multiplier reflecting whether the engine framed the brand favorably or negatively.M(B, Q_i): A binary indicator (1 or 0) scoring whether brand B was cited or mentioned in response to prompt Q_i.
A raw mention count without placement weighting produces misleading results. Ranking as the primary recommended vendor carries higher commercial value than an unlinked footnote citation.
| Placement Position | Placement Score (P_i) | Operational Meaning |
|---|---|---|
| Primary Recommendation | 1.00 | Listed first as the top solution or category leader. |
| Top 3 Shortlist | 0.75 | Included inside a recommended comparison group. |
| Secondary Mention | 0.40 | Mentioned as an alternative or honorable mention. |
| Unlinked Footnote Citation | 0.15 | Sourced in references without in-text recommendation. |
| Omitted | 0.00 | Brand was not mentioned or cited in the model response. |
Why Does AI Share of Voice Differ Across AI Models?
AI Share of Voice differs across AI models because each engine uses distinct training datasets, retrieval algorithms, and recency thresholds. A brand dominating ChatGPT recommendations can register zero visibility in Google Gemini or Perplexity.
ChatGPT (OpenAI GPT-4o / Search)  -> Parametric memory + Bing Index retrieval
Perplexity (Sonar / Pro Search)   -> Multi-source live web crawl + dynamic reranking
Google Gemini (Gemini 1.5 / 2.0)  -> Google Search Index grounding + Knowledge Graph
Claude (Anthropic Claude 3.5)     -> Strict refusal boundaries + pre-trained corpus
Microsoft Copilot                 -> Bing Web Index + Edge DOM contextual grounding
Perplexity and ChatGPT Search execute real-time searches before generating responses. They favor recently published comparison guides, transparent pricing tables, and schema markup. Claude relies more heavily on historical entity consensus within its base training weights.
To build an actionable measurement baseline, read our framework on monitoring AI search visibility for brands. Evaluating performance across multiple platforms prevents blind spots caused by single-engine bias.
How Do You Build an Unbiased Prompt Portfolio for AI SOV?
You build an unbiased prompt portfolio for AI SOV by categorizing queries into four distinct intent tiers and sampling across fixed evaluation windows. An unbalanced prompt set skewed toward branded queries inflates your score and masks competitive vulnerabilities.
1. Unbranded Category Discovery (40% Portfolio Weight)
These prompts represent early-stage software discovery where buyers define functional requirements without naming vendors:
- "What is the best SEO automation platform for enterprise marketing teams?"
- "Which tools automate technical schema markup deployment?"
2. Comparative Evaluation (30% Portfolio Weight)
These prompts reflect buyers evaluating specific trade-offs between known options:
- "Search Atlas vs Semrush vs Ahrefs for agency reporting."
- "What are the most affordable alternatives to Profound AI?"
3. Feature and Compliance Constraints (20% Portfolio Weight)
These prompts simulate procurement committees testing enterprise boundaries:
- "Which AI visibility monitoring tools support custom API webhooks?"
- "Compare SEO rank trackers that offer white-label client portals."
4. Branded Entity Verification (10% Portfolio Weight)
These prompts test whether models accurately report your current capabilities and pricing:
- "How much does Search Atlas cost per month?"
- "Does Search Atlas offer automated URL indexation?"
How Do You Account for Model Stochasticity and Hallucination?
You account for model stochasticity by running automated prompt sweeps across multiple runs and logging exact response variations. Single prompt queries fail statistical significance tests because temperature settings introduce output variance.
A brand may appear in three out of five consecutive runs for the exact same prompt in ChatGPT. Measuring prompt repeatability gives you a consistency score:
Consistency Rate = (Successful Mentions / Total Prompt Runs) × 100A consistency rate below 60% indicates unstable entity authority. When consistency drops, retrieval models struggle to reconcile conflicting third-party documentation.
For a structured review of tracking methodologies, review our guide on choosing AI visibility tracking tools. Automated tracking software automates recurring multi-run testing without manual prompt entry.
How Do You Actionably Increase Your AI Share of Voice?
You actionably increase your AI Share of Voice by addressing the specific citation sources that answer engines retrieve during real-time search passes.
- Identify Cited Information Hubs: Review the sources cited in Perplexity and ChatGPT when your competitors win recommendations. If industry reviews or comparison blogs dominate citations, acquire coverage on those third-party hubs.
- Publish Definitive Category Data: AI models cite unique data, original benchmarks, and clear definitions. Publishing original research encourages models to cite your domain as an authoritative reference.
- Resolve Digital Entity Inconsistencies: Verify that Wikipedia, Wikidata, review directories, and your website state consistent company facts, founding dates, and product categories.
To implement an end-to-end measurement routine, follow our operational LLM visibility tracking plan. Tracking AI Share of Voice on a weekly cadence ensures your product team catches recommendation shifts before organic trial volumes drop.
For automated multi-engine tracking across all major LLMs, explore Search Atlas LLM Visibility to track share of voice, prompt rankings, and competitor movement across one dashboard.